

A research environment built for classical Arabic text
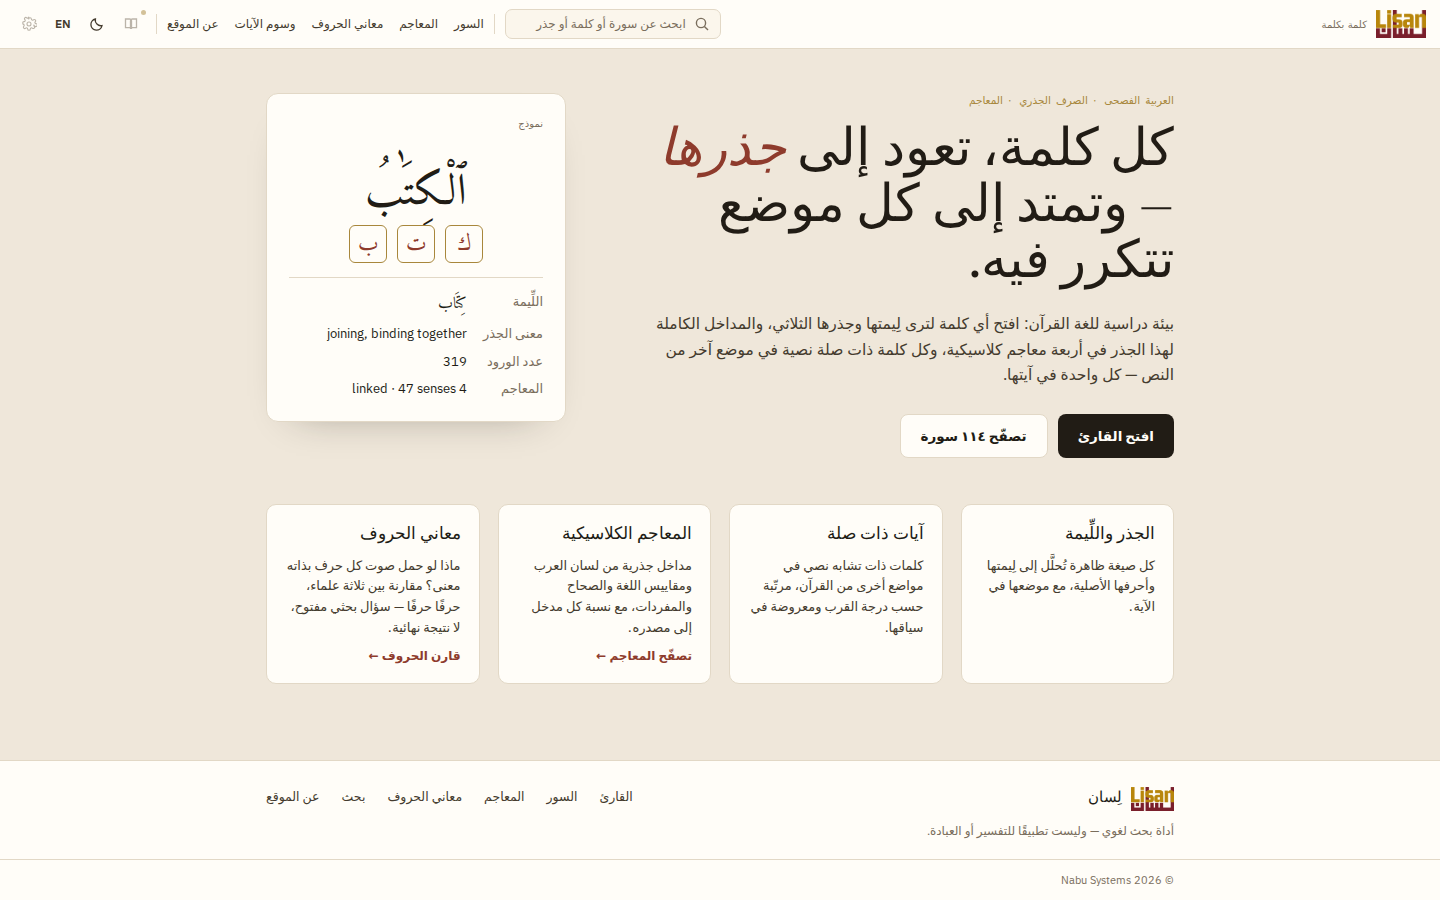
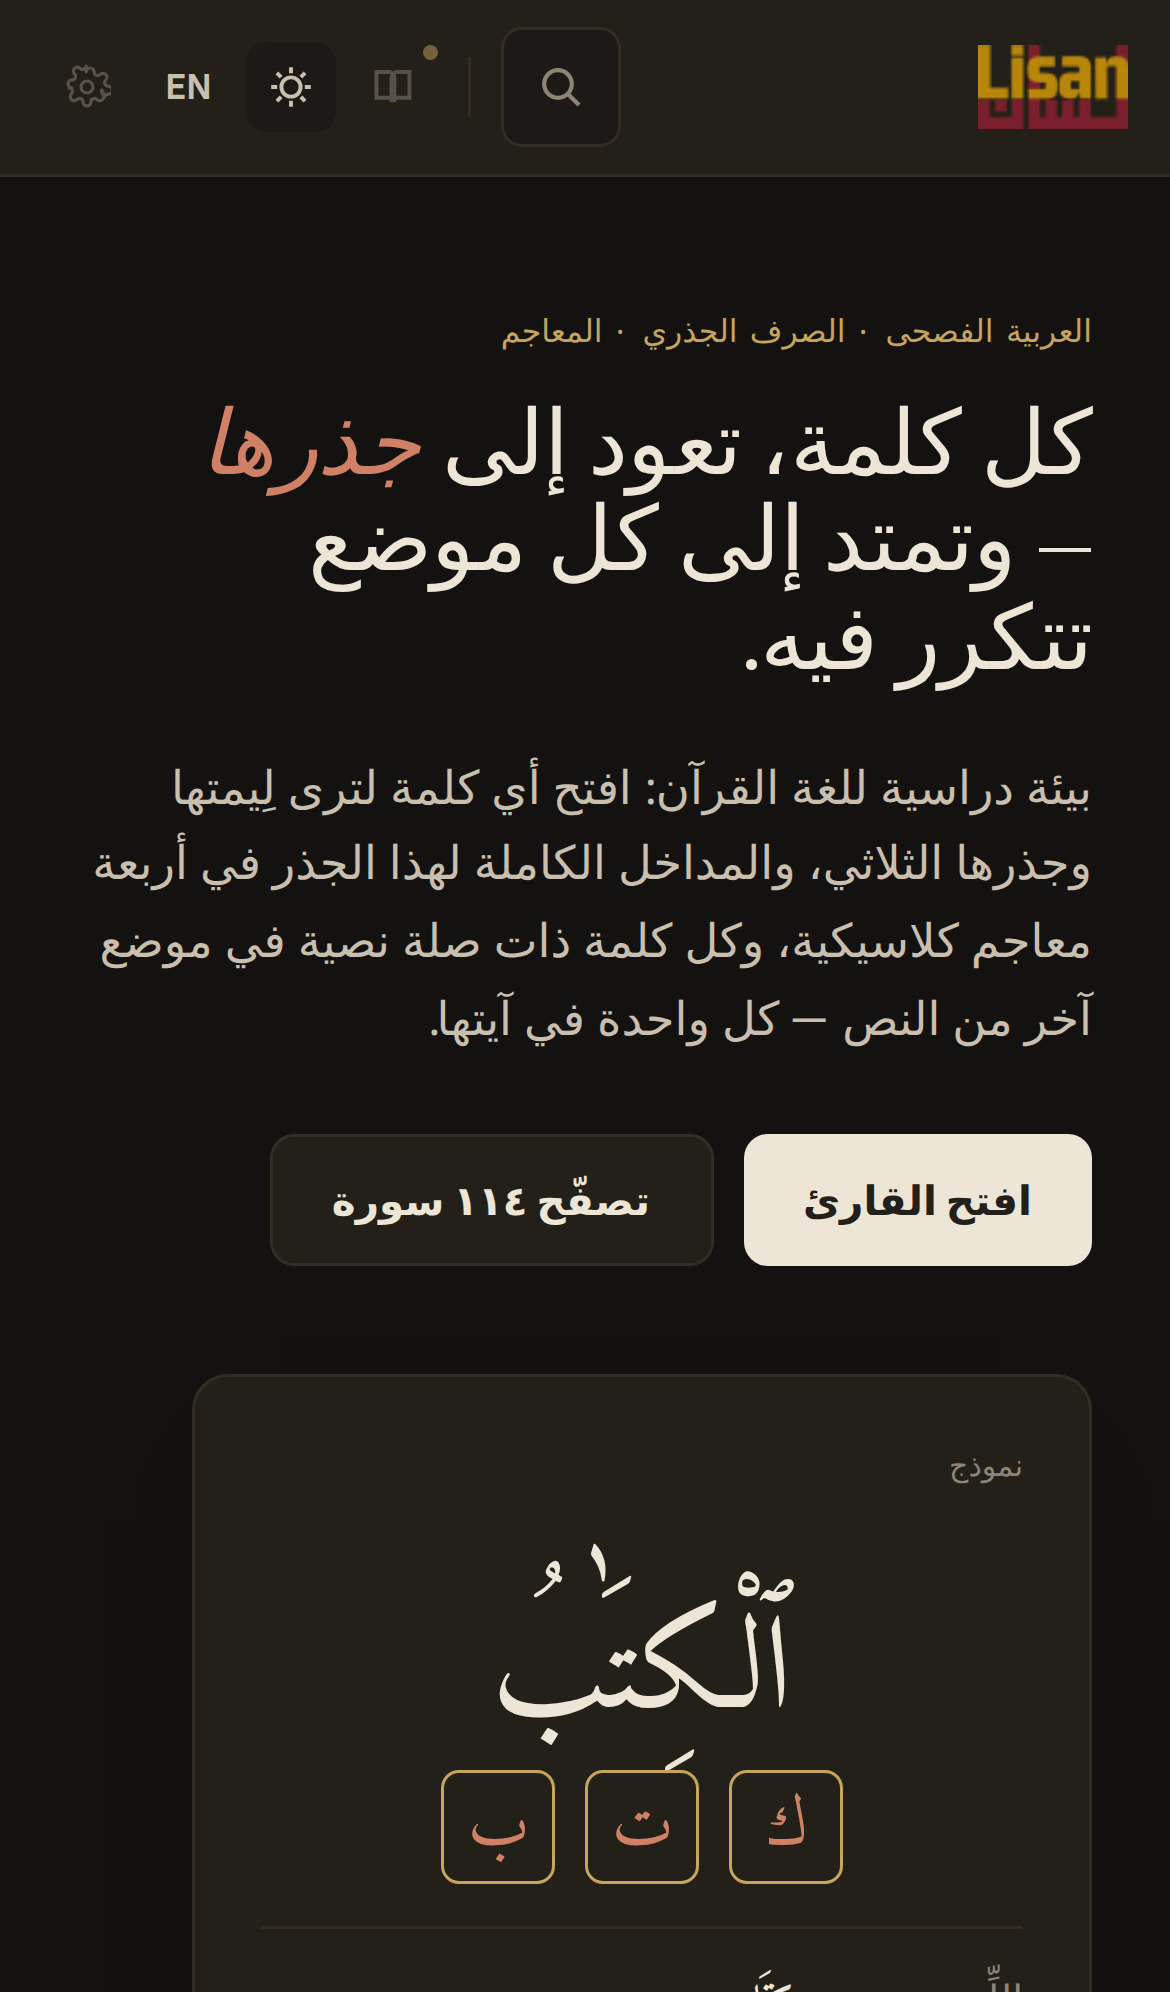
Lisan lets a reader open any word in the Quran's text, see its root and full lexical breakdown, and trace every other place that root or lemma appears, across four classical dictionaries.
Root & lemma tracing
Open any word to see its three-letter root and every other place that root or lemma recurs in the text.
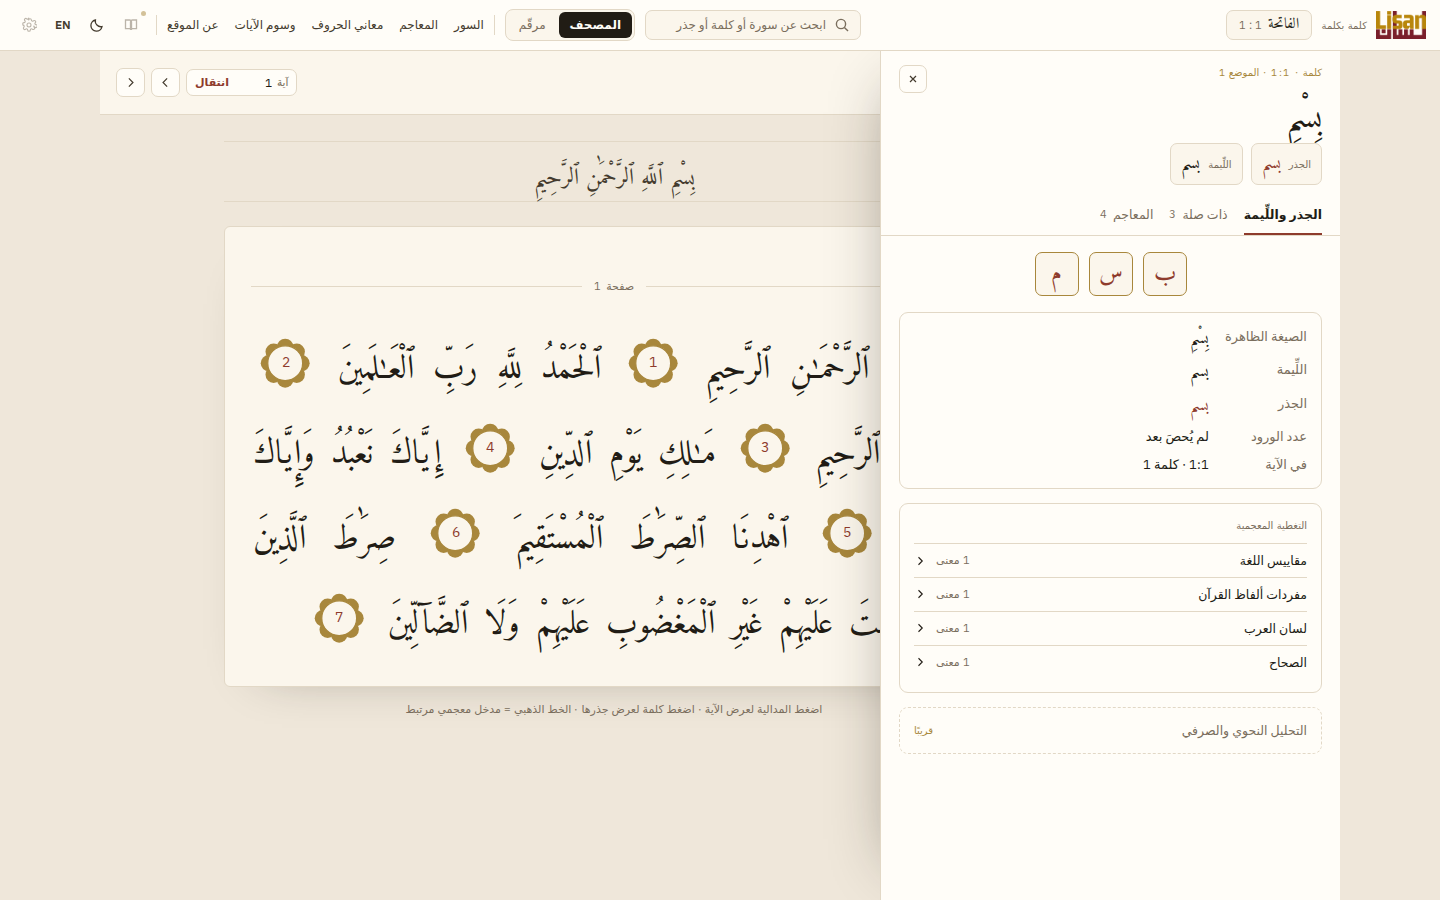
Four classical lexicons
Cross-reference Lisan al-Arab, Maqayees al-Lugha, As-Sihah, and Mufradat Alfaz al-Qur'an from one panel.
Verse tags & analytics
A linguistics-only tag taxonomy with statistical dashboards and a network graph of tag and root co-occurrence.
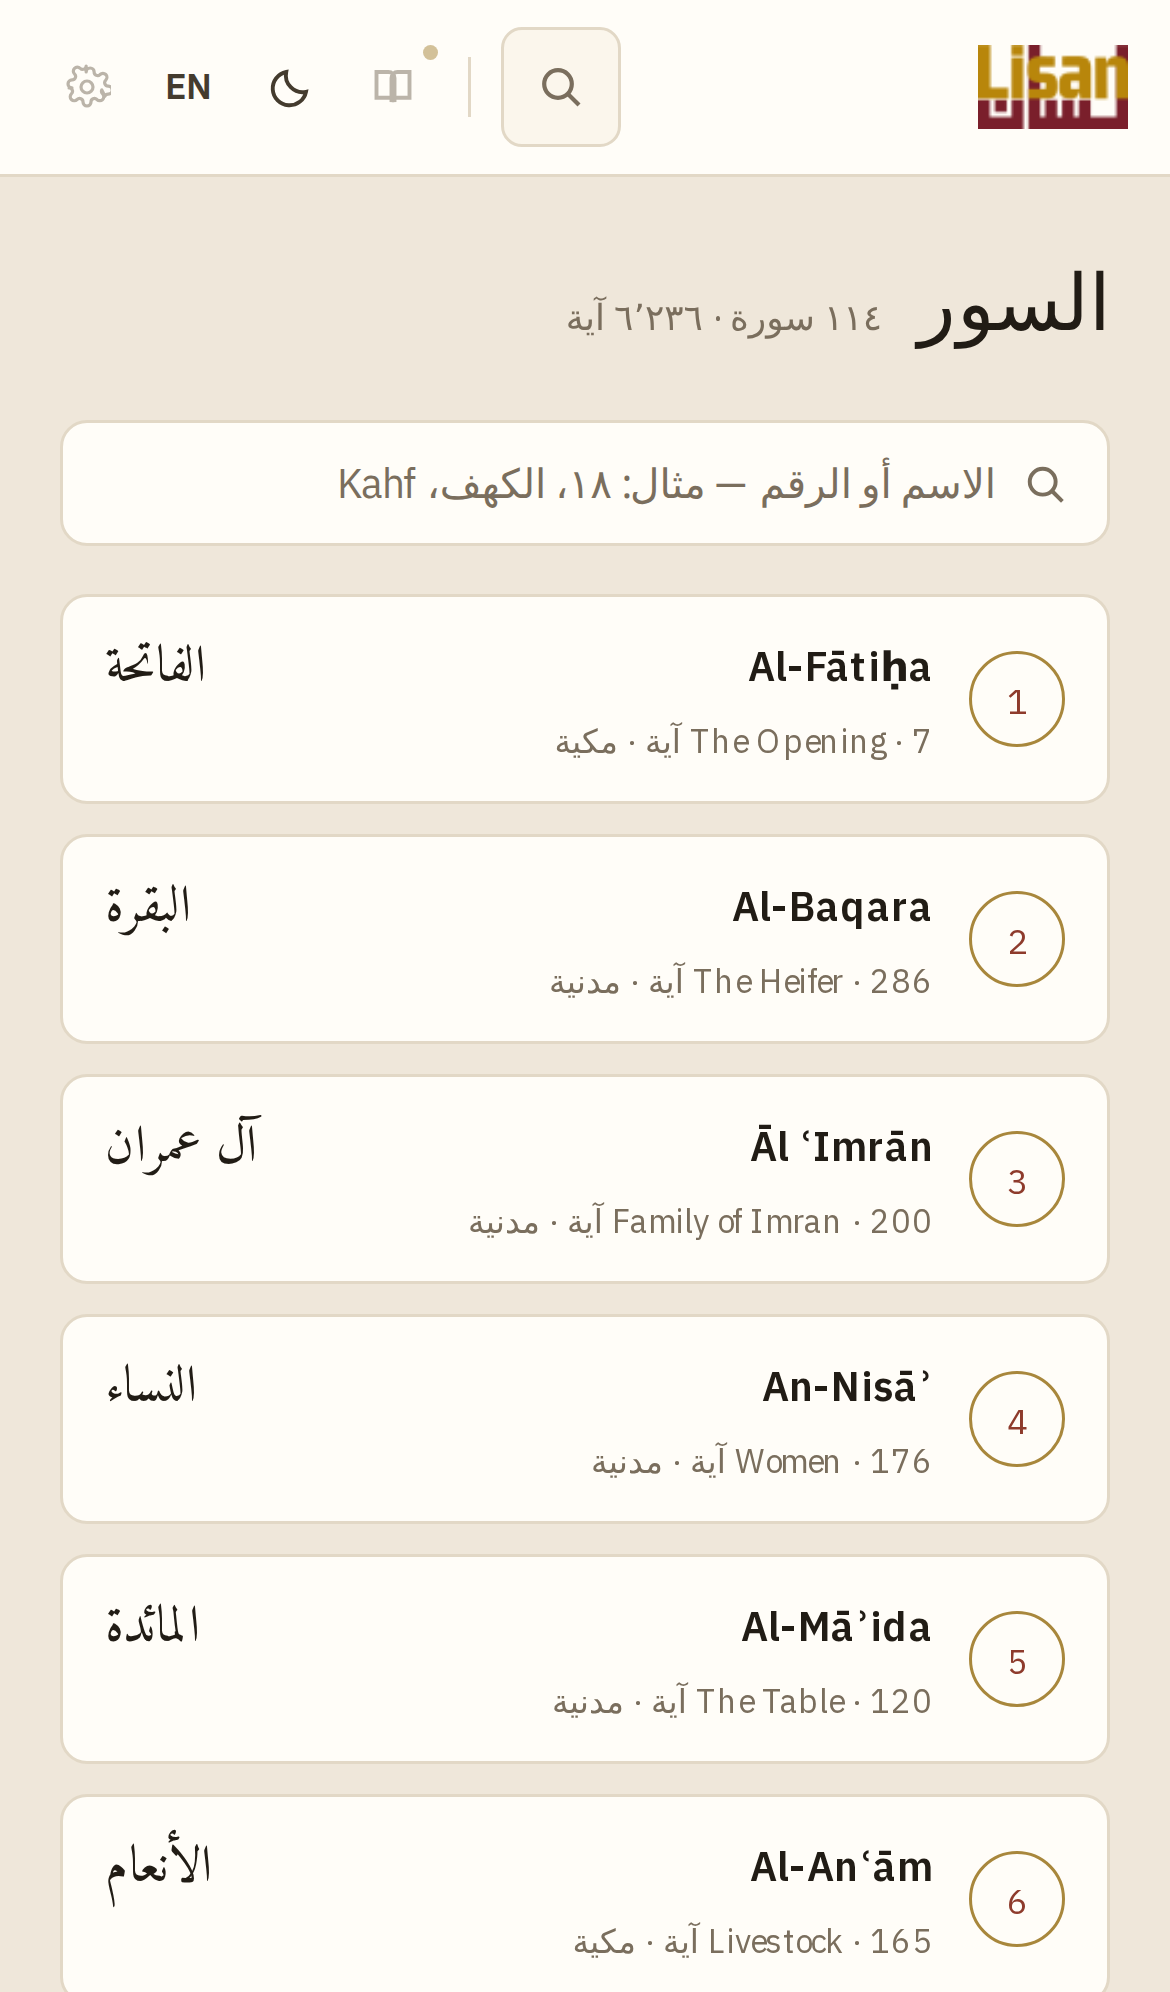
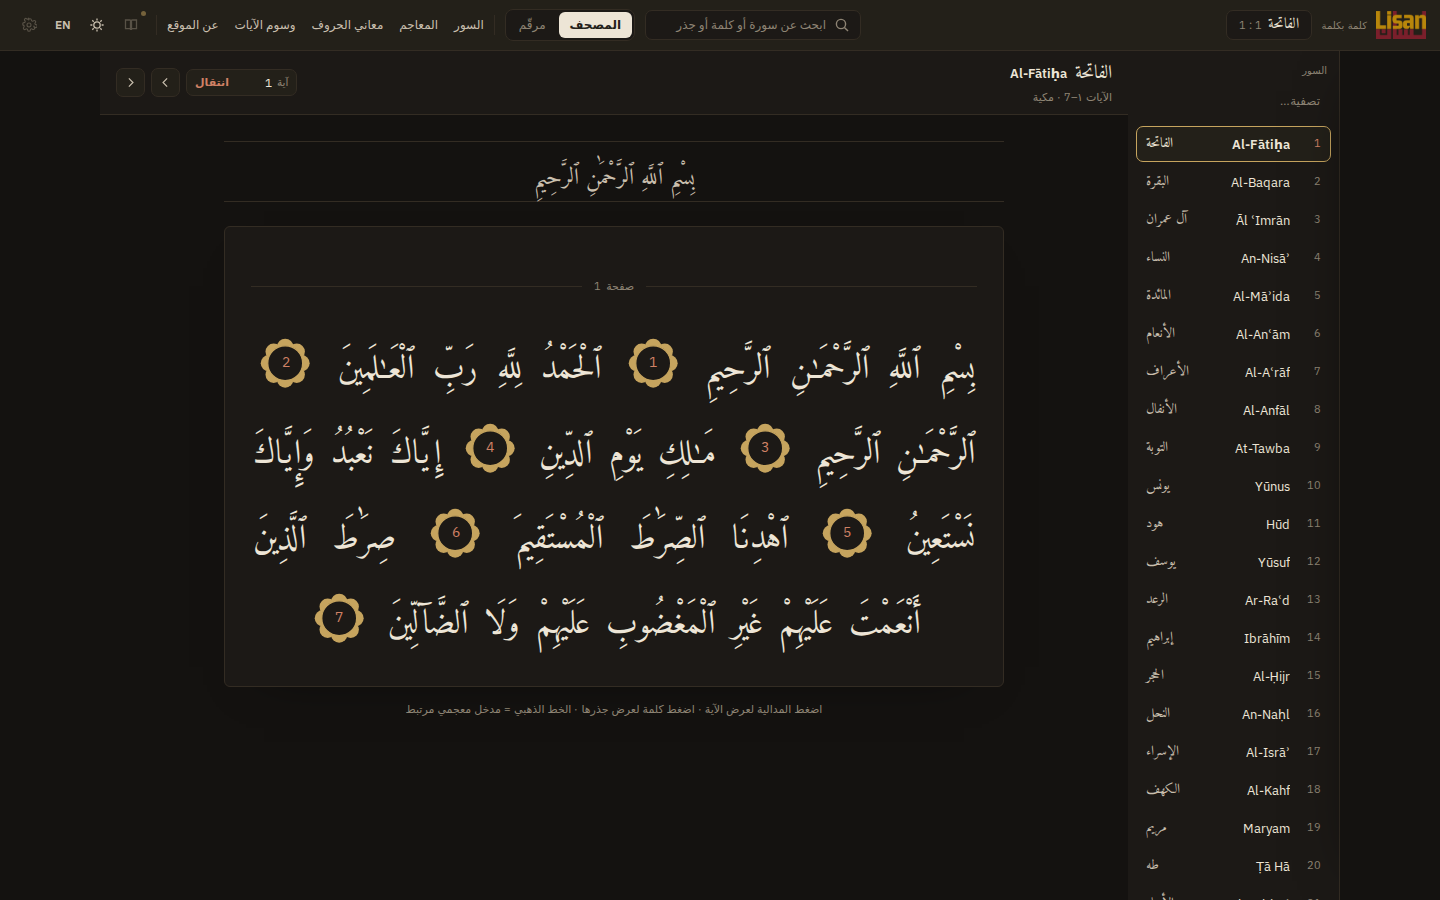
Dark mode & mobile reading
A full dark theme and a responsive reading and search experience across desktop and mobile.
A research environment for word- and root-level study
Lisan pairs a segmented, lemmatized text with a precomputed word-relationship index and four classical Arabic lexicons. It is built as a linguistic research tool, not an app for exegesis or worship.
Classical Arabic text is hard to study at the word and root level
Tracing a word back to its three-letter root, finding every other place that root recurs, and cross-referencing classical dictionaries normally means flipping between separate lexicons and concordances by hand.
Built around how classical Arabic text is actually studied
Lisan combines a segmented, lemmatized text with root tracing and classical lexicons, so word-level research happens in one place instead of across scattered references.
Word-level detail panel
Click any word to see its root, lemma, lexical breakdown, and every related occurrence in context.
Root & lemma concordance
Trace every occurrence of a given Arabic root across all 114 chapters from a precomputed index.
Classical dictionaries
Root-indexed entries from four classical Arabic lexicons, with a frequency count per root.
Uthmani-script reader
A full mus'haf reader, page by page, in Mushaf or numbered-verse view, with dark mode throughout.
A closer look at the product
Lisan's reader, word detail panel, and dictionary views work across a full dark theme and a responsive layout for desktop and mobile study.
Who Lisan is built for
The product is most relevant for linguistics researchers, students of classical Arabic, and anyone tracing roots and lemmas across classical lexicons.
Arabic linguistics researchers
Researchers studying root systems, morphology, and classical usage across the Quran's text.
Classical Arabic students
Students who want to trace a word's root and lemma across every place it recurs in context.
Lexicon and dictionary readers
Anyone who wants classical lexicon entries indexed by root rather than searched one dictionary at a time.
A research tool, not an app for exegesis or worship
Nabu built Lisan so a reader could trace a word to its root, and that root to every other place it recurs, without flipping between separate lexicons by hand. The product is scoped to root- and lemma-level tracing against primary classical sources.
Product direction
Lisan reflects Nabu's view that studying the Quran's Arabic at the word and root level deserves its own dedicated environment, kept deliberately separate from exegesis or devotional use.
Product inquiry
Discuss Lisan with Nabu
If you are interested in Arabic linguistic tooling, text segmentation, or root-level research environments, Nabu can walk you through Lisan and the approach behind it.